You can analyze qualitative data without dedicated software by reading your transcripts, labelling meaningful passages with short codes, defining those codes in a codebook built in a spreadsheet, and grouping them into themes you can defend with participant quotes. What you cannot skip is the method. The tool saves time; it does not think for you.
Plenty of people hit this wall. A PhD student opens a licence agreement for software she cannot justify on a stipend. A market researcher has eight focus group transcripts and three weeks. A UX team has a hundred support tickets and no budget line for a QDA platform. In each case the honest answer is the same: the barrier is rarely money for the software. It is not knowing what to do once the file is open, which is a method problem rather than a tooling problem.
This guide is the manual workflow I would hand someone on day one. It works with a word processor, a spreadsheet, pens and paper, and about two to four hours per interview once you get the rhythm. Reviewed for 2026.
Table of Contents
- What You Need
- Step-by-Step
- 1. Define the question and choose a unit of analysis
- 2. Prepare and organize the data
- 3. Read the data repeatedly and note initial impressions
- 4. Code the most important passages
- 5. Group codes into broader categories and themes
- 6. Build an evidence trail and interpret patterns
- 7. Check credibility and report the analysis
- A worked example, end to end
- How long this takes, and when to switch to software
- Where AI helps, and where it fails
- Common Mistakes
- Frequently Asked Questions
- Does using a spreadsheet or Word count as using software?
- Is there a free alternative to NVivo for qualitative coding?
- Can ChatGPT do qualitative coding, or is NVivo better?
- How many interviews are enough for qualitative research?
- Is 20 respondents enough for a qualitative study?
- Should I code line by line or by paragraph?
- Conclusion
What You Need
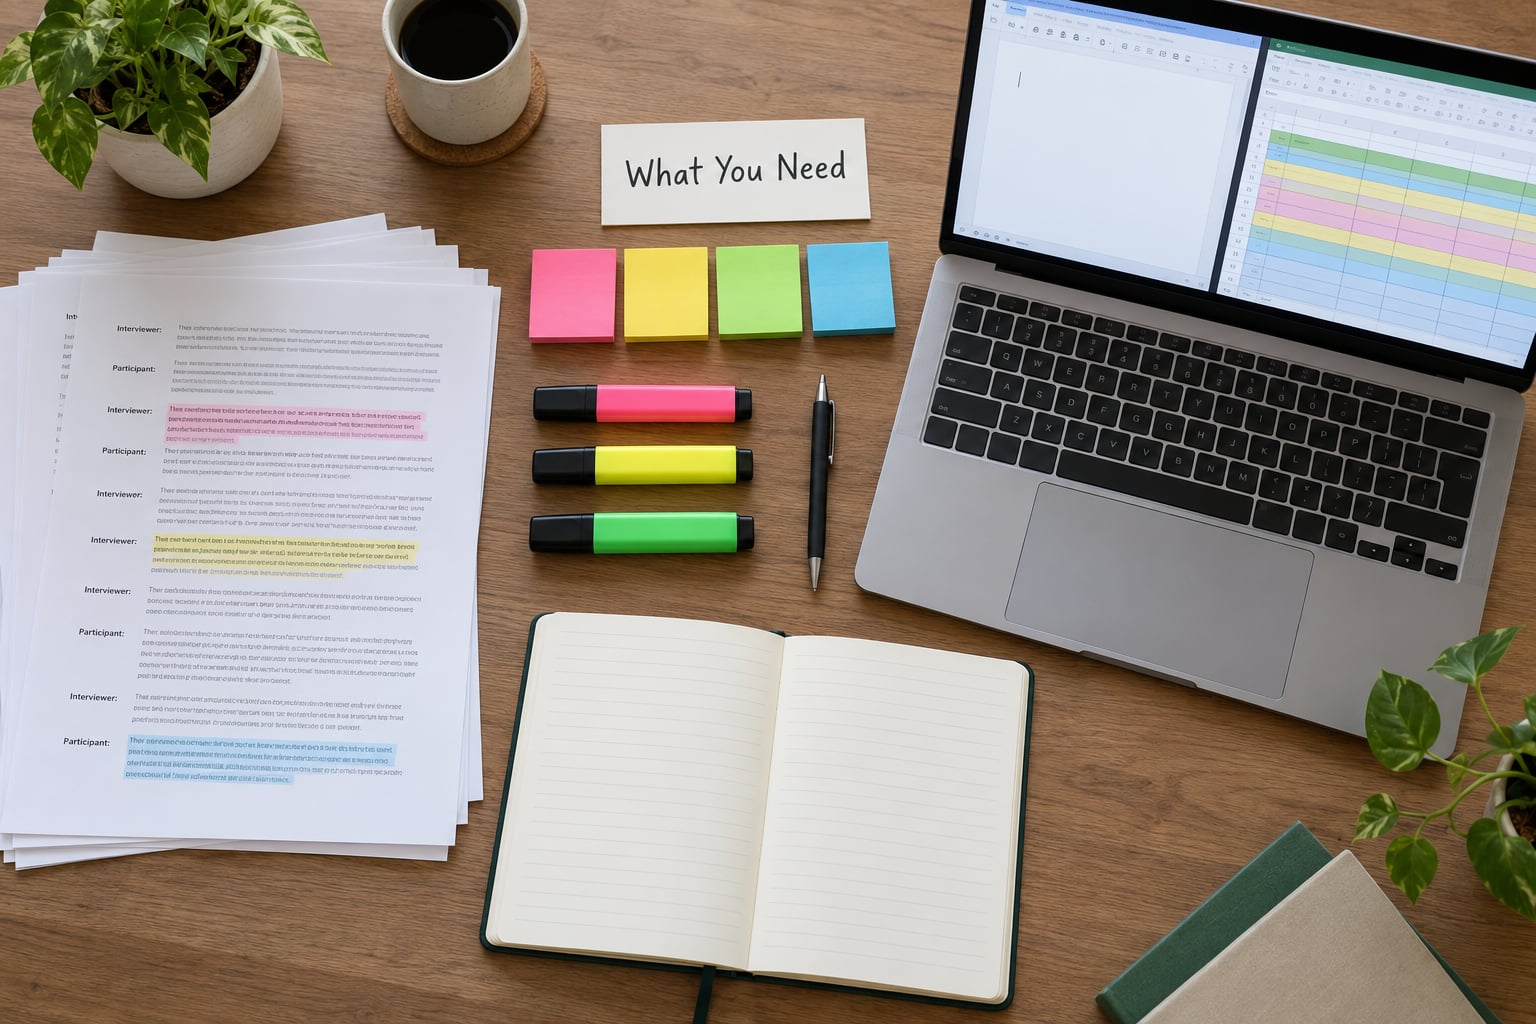
To analyze qualitative data without software you need five things, and only one of them is electronic. Have your transcripts in a consistent format, a research question written down before you touch the data, one document or spreadsheet per working file, a physical space to sort things, and a simple coding convention you can keep consistent for the whole project.
The spreadsheet is not the enemy here. Students often hear “without software” and assume it means paper only, then print forty pages and lose them. Word or Google Docs plus a spreadsheet covers the vast majority of small studies, and the community treats that combination as legitimate rather than as a compromise.
| Job | What to use | Why it works |
|---|---|---|
| Store and read transcripts | Word or Google Docs, one file per participant, named P01, P02 | Comments and highlight colours replace tagging features, and you already have search |
| Hold the codes | A spreadsheet: columns for code, definition, include when, exclude when, example quote | Sortable, filterable, and it doubles as the codebook you hand in |
| Track who said what | A second tab, participant down the side, code across the top | Shows coverage and gaps at a glance without any querying tool |
| Sort themes physically | Index cards, sticky notes, or cut-up printed excerpts | Moving a card with your hand is a different cognitive act from renaming a label |
| Transcribe audio | Your phone voice memo for capture, and browser-based transcription for a first pass | You correct it against the recording rather than trusting it |
| Keep the audit trail | One folder: transcripts, codebook, coding log, analytic memos | Supervisors and journals ask for exactly this set of documents |
Two conventions save hours later. Give every participant a neutral identifier and keep the link between P07 and the real name in a separate file, because anonymization has to survive the whole project, not just the final write-up. And decide on the transcription standard before you start: verbatim keeps every filler and false start, clean verbatim removes them and leaves meaning intact. Clean verbatim is usually the right call for interview and focus group data, verbatim when you are studying turn-taking or interruption.
Step-by-Step
Here is the full manual workflow. Each step produces a file or a written note that becomes an input to the next one, so if you get to the end and cannot show your working, a step was skipped.
1. Define the question and choose a unit of analysis
Turn a broad topic into a question you could actually answer with quotes. “How do new hires experience onboarding” is a topic; “What makes new hires feel competent in their first month” is a question that tells you what to code for. Write it on the first page of your working document and leave it there.
Then pick your unit of analysis, which is the size of the thing you attach a code to. Sentences, paragraphs, and whole interview segments all work. Sentences give you the finest retrieval but produce a hundred tiny codes by transcript three. Paragraphs are the usual choice for interview work, and many people move by meaning rather than by fixed size: attach the code to the stretch of talk that carries the thought.
You know the step worked when you can state, in one sentence, what a code will be a label for. If you cannot, the question is still too loose.
2. Prepare and organize the data
Read one transcript straight through without coding it, and clean it as you go. Add speaker labels on every turn, note the date, duration, and setting in a header block, and mark inaudible stretches as [unclear] rather than guessing at the words. Remove names, employer names, and any identifying detail, and keep a copy of the key in a separate encrypted place if you need to re-identify later.
Order the files before you start, not during. The simplest workable order is by participant ID rather than by interview question, because batching by question forces you to jump between files constantly once you are twenty transcripts deep. Number them 01, 02, 03 so a late addition does not renumber everything.
You know it worked when you can open any file and immediately tell who spoke, when, and under what conditions.
3. Read the data repeatedly and note initial impressions
Now read everything, without coding. Do at least two full passes. The goal is familiarity, not extraction: you are learning the shape of the material, the vocabulary people use, and the moments where something unexpected happened.
Keep a running document of first impressions. Write what struck you, where you noticed a shift in tone, which anecdotes came up more than once, and any moment that puzzled you. Separate observation from interpretation as you write, because blending them is where most beginner analysis quietly goes wrong. “Three participants describe the handover as abrupt” is an observation. “The handover is a problem” is an interpretation you are not ready to make yet.
You know it worked when you can describe each transcript in two or three sentences without checking.
4. Code the most important passages
Attach short labels to meaningful passages. This is first-cycle coding, or open coding, and the label can be anything that helps you retrieve the passage later. Keep it short: two or three words, written in the participant’s language where their phrasing is doing real work.
Five coding styles cover most needs, and mixing them within one transcript is fine as long as you record what you did.
- Descriptive codes name what is happening. “Asks colleagues for help,” “Screens calls during lunch.”
- In vivo codes use the participant’s own phrase. “It felt like a fishbowl,” “Nobody told me the rules.”
- Process codes mark movement or stages. “Avoids the team channel,” “Confronts the manager,” “Withdraws.”
- Emotion codes capture affect. “Anxious about the review,” “Relieved when it passed.”
- Structural codes flag the conditions or context of a stretch of talk. “First month,” “Remote team,” “After the reorganisation.”
In a word processor, put codes in comments or use highlight colours rather than typing into the body, so the transcript stays readable. One colour per parent code, and write the colour legend at the top of the file. With a spreadsheet, add a column called Codes and keep one row per coded passage with the participant ID, the page or paragraph, the quote, and the code.
Code the first two or three transcripts freely and openly, then stop and write the codebook before going further. This is the single most useful habit in the whole process, and it is where the spreadsheet earns its place.
You know it worked when every code you have used has a one-line definition and an example.
Your codebook needs five columns: code name, definition, include when, exclude when, and one example quote. The include and exclude columns do the heavy lifting, because they are what let a second coder, or you in month three, apply the code the same way. A codebook without exclusion rules is a wish list.
5. Group codes into broader categories and themes
Codes are labels. Themes are arguments. A code called “asks colleagues for help” is a topic; a theme that claims the organisation routes all uncertainty through informal social channels rather than documented process is an interpretation, and only the second one goes in your findings section. Most weak student analysis collapses at exactly this point.
Second-cycle coding is the merge pass. Print the code list, cut the codes onto cards, and shuffle them on a table. Move overlapping codes together. Split codes that hide two different ideas under one label. Group the survivors into a smaller number of broader categories, then ask what each group is really about in one sentence.
Do not force everything into a pattern. Keep the awkward cases, the one-off remarks, the account that contradicts your main theme. Those are your negative cases, and reporting them is what separates an analysis from a summary.
Frequency is not importance. A code that appears twice can carry more of your argument than one that appears in every transcript, and treating counts as importance is the most common error in hand-coded work. Use counts to show coverage, not to pick winners.
6. Build an evidence trail and interpret patterns
Every theme needs a trail back to the data. Use a matrix sheet with participants down the side and themes across the top, and in each cell put a short summary, one representative quote, and any exception. When a cell is empty, that is a finding about coverage, not a formatting problem.
Run constant comparison while you write: hold a theme against one full transcript and ask whether the whole transcript supports it, then against the one that disagrees most. That last step is where the interesting qualification usually lives. Write each theme as a claim, then support it with two or three quotes from different participants so it does not rest on one vivid story.
Stay inside what the data proves. Four people describing a fast handover is four accounts, not a finding about your industry. Say what you saw, how often, in whose words, and where the evidence runs out.
7. Check credibility and report the analysis
Four checks are available to you by hand. Coverage: does every participant appear in the matrix, and if not, do you know why. Consistency: pick ten passages at random and check that your codebook would have produced the same code as you actually applied. Negative cases: have you looked for the account that contradicts your main theme rather than only for confirming ones. Reflexivity: write a short memo on where you came from, what you assumed, and which passages you found yourself reading differently than expected.
On consistency, note the ceiling. Reported agreement between two human coders on a codebook in one surgical qualitative study was 95.1 percent, with a kappa of 0.754, and the AI-drafted codebook scored 92.3 percent at kappa 0.638. Experienced people do not agree perfectly, so a high but imperfect agreement figure is normal rather than a failure.
Your write-up needs four documents, and all four exist in a folder of ordinary files: the codebook, a coding log recording what you coded and when, analytic memos written as you went, and a methods paragraph describing the approach in enough detail that someone could repeat it. A typical methods statement names the tradition you followed, the number of participants, the coding style, the steps of your analysis, and the quality checks you ran. If your study went through ethics review, say how consent, anonymization, and storage were handled.
You know the analysis is finished when you can write a coherent three-thousand-word account, back every claim to a coded passage, and name the limitations without flinching.
A worked example, end to end
Here is the whole chain on one short segment, because this is the part that usually gets skipped and it is the part that makes the difference.
Participant 04, describing the first month: “You just sit there and listen. The first fortnight I asked three people the same question and got three different answers. Nobody told me the rules because the rules are really just what Al does, and Al had gone on leave.”
| Stage | What it produces here |
|---|---|
| First-cycle codes | Watches without a task; asks around for information; gets conflicting answers; rules are tacit; key person absent |
| Codebook entry | Tacit onboarding: include when a participant describes learning how things are done from observation or other people rather than from any written instruction; exclude when someone received a documented checklist |
| Second-cycle grouping | Merged “asks around for information” and “watches without a task” into Informal information-seeking; kept “key person absent” separate as a structural condition |
| Theme | Onboarding knowledge circulates through observation and personal contact rather than documentation, which leaves new hires dependent on whoever happens to be available |
Note what the example does not do. It does not generalise to other organisations, it does not count how many people said this, and it does not claim the manager caused anything. It says what four participants described, in their words, and stops there.
How long this takes, and when to switch to software
Rough planning figures, since nobody publishes these. Allow two to four hours per interview for first-cycle coding plus your codebook, more like six to eight for your first two transcripts. A one-hour interview transcript runs to roughly ten pages double-spaced, and transcribing by hand takes about five to six hours, which is why the free transcription pass is worth correcting. Plan in rounds: code three interviews, revise the codebook, code the rest, then do a full second cycle over everything at the end.
Vendors are right that manual coding does not scale, and pretending otherwise helps nobody. The honest crossover point looks like this.
| Situation | Verdict |
|---|---|
| Fewer than about 20 interviews, one coder | Stay manual. Word, a spreadsheet, and cards handle this comfortably |
| 20 to 50 interviews, one coder | Still manual, but batch by participant, rotate code passes, and keep the coding log tight |
| More than two coders on the same data | Consider a tool. Consistency checks and a shared codebook get expensive fast by hand |
| More than roughly 60 interviews, or a tight deadline | Use a tool, or accept a smaller dataset. Cutting the sample is the better compromise |
| Thousands of open-ended responses, or keyword retrieval across a corpus | Software. Manual coding does not reach this |
| You need to teach the analysis to others | Either works. Keep the codebook and memos regardless |
Free options exist and they are not all equal. Some open-source tools are genuinely free and handle small projects, which answers the free alternative question honestly, and an academic licence route through your library may cover the paid platforms at no cost to you. Ask before you buy. If the tool needs a steep learning curve you will not have time for, the spreadsheet is still the better decision, because a method you actually use beats a system you abandon in week three.
Where AI helps, and where it fails
Large language models are useful in two narrow places here. They can draft a first codebook from a handful of excerpts so you have something concrete to argue with, and they can summarise long stretches of transcript so you know what you are coding before you read it line by line. Treat both as a starting draft, never as output.
They fail in predictable ways. Sarcasm and understatement get read literally, domain jargon gets normalised into generic language, in vivo codes lose the participant’s exact phrasing, and a long transcript pasted into a chat window produces a confident summary that quietly drops the awkward exceptions you needed. In the study above, the AI-drafted codebook reached 92.3 percent agreement with expert coders against 95.1 percent for the human codebook, and reported agreement in the 85 to 90 percent range is typical elsewhere, with sarcasm and jargon the recurring failure cases.
Whichever route you take, disclosure is the part people skip. If AI touched the data, say so in your methods paragraph, name what it did, and keep the human validation step explicit. Do not paste identifiable interview data into a public tool without checking your consent form and your institution’s data protection rules first, because your participants agreed to talk to you, not to a third-party service.
Common Mistakes
Coding every sentence is the first one, and it is almost always a sign of anxiety rather than rigour. Code meaning, not volume; if a passage carries nothing for your question, leave it alone. The fix is to fix a unit of analysis before you start and stick to it, which is why step 1 exists.
Deciding your themes in advance is the second. Some studies legitimately start deductive, especially when you are testing a framework from prior work, but a codebook written before a single transcript is read is deduction wearing a lab coat. Ask yourself whether your categories came from the literature or from the participants, and if the answer is only the literature, expect the analysis to confirm what you already believed.
Losing the case is the third and the sneakiest. Once everything is fragmented into coded pieces, the person disappears. Keep one running summary per participant, and re-read one full transcript end to end every few sessions.
Treating frequency as importance is the fourth. Counts tell you what was common, not what mattered to your argument, and building a findings section on the most frequent code is how a study ends up reporting its dataset instead of answering its question.
Reporting themes without evidence is the fifth. A theme with no quote, no code definition, and no negative case is an impression. If you cannot attach one specific passage to it, it is not ready for the findings section.
Two more failure modes are worth naming. Code proliferation shows up as 200 codes by transcript six, which is really a missing second-cycle pass wearing a disguise. Code drift shows up when the same label means slightly different things in transcripts one and twenty, which is what the codebook’s include and exclude columns exist to prevent.
A few habits fix most of this. Print your code list every ten transcripts and cut it up again, because the merge that is obvious in month three is invisible in week one. Keep a coding log with dates, because recovering your own reasoning later is otherwise impossible. Write a one-page reflexivity memo before you start and another at the end, and diff them. And ask a colleague to look at two transcripts and code one passage, purely to see how far apart you are.
Frequently Asked Questions
Does using a spreadsheet or Word count as using software?
It counts, and that is fine. When researchers say qualitative analysis without software, they mean without dedicated computer-assisted analysis platforms such as NVivo, ATLAS.ti or MAXQDA, not without a computer. A word processor with comments, a spreadsheet holding your codebook, and a folder of memos is a complete workflow for a modest number of interviews.
Is there a free alternative to NVivo for qualitative coding?
Several open-source options are genuinely free and handle small projects well, and many universities give library access to the paid platforms at no personal cost. The honest answer is that a spreadsheet and a word processor will carry you through a modest interview study. Past roughly 60 interviews, or with multiple coders, the free tools become worth the learning time.
Can ChatGPT do qualitative coding, or is NVivo better?
ChatGPT can draft a first codebook and summarise long transcript stretches, which saves hours on the early passes. It is weaker on sarcasm, domain jargon, and preserving the participant’s exact phrasing, and it can quietly drop inconvenient exceptions. It is not a substitute for coding, and a paid platform is not automatically better. The method is what makes the analysis defensible.
How many interviews are enough for qualitative research?
Enough to reach code saturation, meaning the last few interviews add few or no new codes to your codebook rather than enough to reach a statistical number. For most interview studies that lands somewhere between 15 and 30 participants, and tight, homogeneous groups reach it faster. If new codes keep appearing, keep going. Coding is a cycle, not a single pass.
Is 20 respondents enough for a qualitative study?
Twenty is a defensible number for many interview or focus group studies, especially when participants are similar and the topic is narrow. It is too few if you are chasing rare experiences, comparing distinct groups, or writing a dissertation with a broad claim. Judge it by whether new interviews stopped producing new codes, not by a round number.
Should I code line by line or by paragraph?
Code by meaning, which usually means paragraph-sized stretches. Line-by-line coding is precise and standard in grounded theory, but it produces a very large number of small codes and slows you down. Pick your unit of analysis before you begin and stay consistent, because switching mid-project is what makes a codebook drift and your counts meaningless.
Conclusion
To analyze qualitative data without software, write the question down, prepare and number the transcripts, read them twice before coding anything, label meaningful passages with short codes, write a codebook with include and exclude rules, cut the codes up and merge them into themes, build a matrix so every theme points back to quotes, and document the whole thing. That set of files is what a supervisor, a journal, or a client will actually ask to see.
Start today rather than planning further. Take your first three transcripts, code them freely for an hour each, then stop and write the codebook before you touch a fourth, because the codebook is where the method begins and where most of the fear lives.